Data Engineering · dbt/Snowflake
H-1B LCA Disclosure Analytics Pipeline
Aarya Bhivsanee built an ELT pipeline that loads U.S. Department of Labor H-1B LCA disclosure files into Snowflake and models them with dbt in RAW, staging, intermediate and marts layers, reconciling schema drift and normalising mixed wage units into one annualised figure.
Overview
This one started as a data engineering exercise and became a question worth answering: how is H-1B sponsorship actually distributed across employers, industries, and roles, especially in the NY/NJ tech market?
Approach
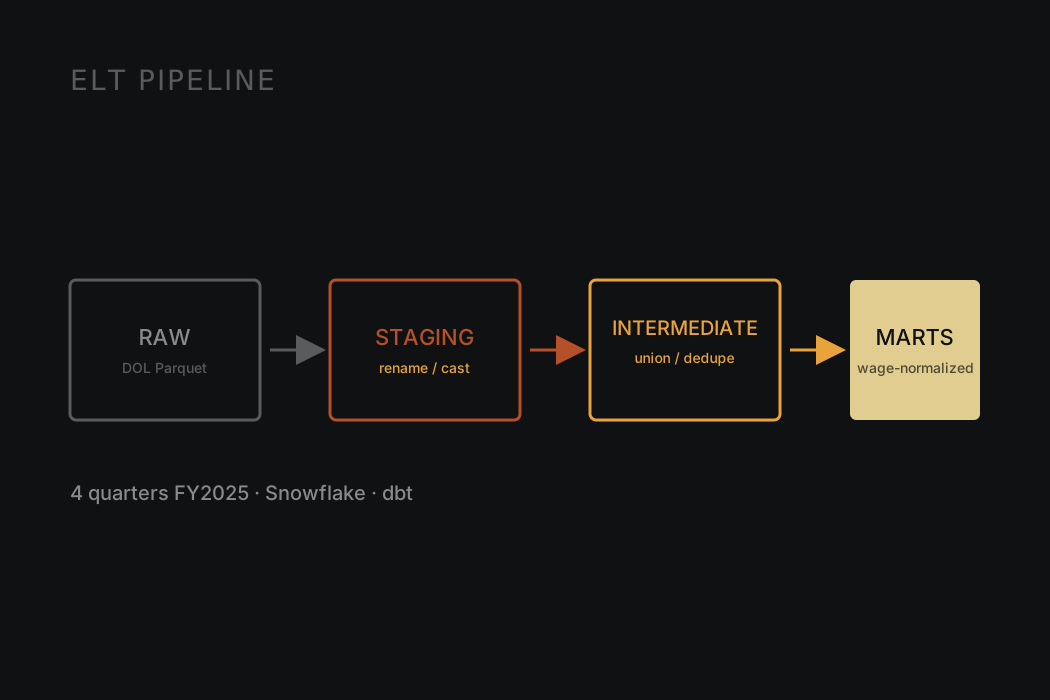
The pipeline moves DOL's quarterly LCA disclosure Excel/Parquet files into Snowflake, then through dbt in explicit layers — RAW (an untouched mirror of the source), staging (rename/cast only), intermediate (union all 4 quarters, dedupe to one row per case), and marts (wage-normalized, ready for BI). Every schema name signals exactly what's been touched, so nothing gets quietly patched in the warehouse.
Results
- Built an ELT pipeline from raw DOL Excel/Parquet files into Snowflake, layered through dbt as RAW → staging → intermediate → marts, so every transformation is visible in version control, not patched silently in the warehouse.
- Reconciled real source inconsistencies explicitly in staging: a hyphen-vs-underscore column rename between Q1 and Q2–Q4, and nanosecond Unix timestamps cast to real dates.
- Normalized wages mixing Hour/Week/Bi-Weekly/Month/Year units into one annualized figure, flagging implausible values instead of silently guessing or dropping them.
- Deduplicated four quarters of FY2025 LCA disclosures down to one row per case, tracking H-1B sponsorship by employer, industry, and role across the NY/NJ tech market.
The real work was in the edge cases the source data doesn't hand you cleanly: Q1's raw schema uses a hyphenated column name that Q2–Q4 don't, dates arrive as nanosecond Unix timestamps instead of real dates, and wages mix Hour/Week/Bi-Weekly/Month/Year units in the same column. I normalized all of it to an annualized figure in the marts layer — and where a value was implausible but plausibly just mislabeled, I flagged it in a separate column instead of silently correcting or dropping it. The goal throughout: every transformation decision stays visible and defensible, not buried.
Tools
- Snowflake
- dbt
- SQL
- ELT pipeline design